|
DFT-EFE
|

|
|
DFT-EFE
|
|
Stateless class of static functions for spin-aware projection and rotation of product-space multivectors. More...
#include <MultiVectorOps.h>
Static Public Member Functions | |
| template<typename ValueTypeOperator , typename ValueTypeOperand , utils::MemorySpace memorySpace> | |
| static void | project (const OperatorContext< ValueTypeOperator, ValueTypeOperand, memorySpace > &Op, MultiVectorProductSpaceBlocked< ValueTypeOperand, memorySpace > &X, std::vector< ScaLAPACKMatrix< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand > > > &Ps, const ElpaScalapackManager &elpa, std::shared_ptr< MultiVector< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand >, memorySpace > > &scratchXin, std::shared_ptr< MultiVector< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand >, memorySpace > > &scratchXout, std::shared_ptr< MultiVector< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand >, memorySpace > > &scratchXinSmall, std::shared_ptr< MultiVector< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand >, memorySpace > > &scratchXoutSmall) |
| Blocked overload (collinear, MultiVectorProductSpaceBlocked). More... | |
| template<typename ValueTypeOperator , typename ValueTypeOperand , utils::MemorySpace memorySpace> | |
| static void | project (const OperatorContext< ValueTypeOperator, ValueTypeOperand, memorySpace > &Op, MultiVectorProductSpace< ValueTypeOperand, memorySpace > &X, ScaLAPACKMatrix< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand > > &P, const ElpaScalapackManager &elpa, std::shared_ptr< MultiVector< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand >, memorySpace > > &scratchXin, std::shared_ptr< MultiVector< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand >, memorySpace > > &scratchXout, std::shared_ptr< MultiVector< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand >, memorySpace > > &scratchXinSmall, std::shared_ptr< MultiVector< blasLapack::scalar_type< ValueTypeOperator, ValueTypeOperand >, memorySpace > > &scratchXoutSmall) |
| Coupled overload (unpolarized S=1 / non-collinear S=2, MultiVectorProductSpace). More... | |
| template<typename ValueType , utils::MemorySpace memorySpace> | |
| static void | rotate (MultiVectorProductSpaceBlocked< ValueType, memorySpace > &X, const std::vector< ScaLAPACKMatrix< ValueType > > &Qs, const ElpaScalapackManager &elpa) |
| Blocked rotate overload (collinear, MultiVectorProductSpaceBlocked). More... | |
| template<typename ValueType , utils::MemorySpace memorySpace> | |
| static void | rotate (MultiVectorProductSpace< ValueType, memorySpace > &X, const ScaLAPACKMatrix< ValueType > &Q, const ElpaScalapackManager &elpa) |
| Coupled rotate overload (unpolarized / non-collinear, MultiVectorProductSpace). More... | |
| template<typename ValueType1 , typename ValueType2 , utils::MemorySpace memorySpace> | |
| static void | copyToBatch (const MultiVectorProductSpace< ValueType1, memorySpace > &X, size_type srcStart, size_type numVecBatch, MultiVector< ValueType2, memorySpace > &Xbatch, LinAlgOpContext< memorySpace > &context) |
| template<typename ValueType1 , typename ValueType2 , utils::MemorySpace memorySpace> | |
| static void | copyFromBatch (const MultiVector< ValueType1, memorySpace > &Ybatch, size_type dstStart, size_type numVecBatch, MultiVectorProductSpace< ValueType2, memorySpace > &Y, LinAlgOpContext< memorySpace > &context) |
Stateless class of static functions for spin-aware projection and rotation of product-space multivectors.
project() computes P = X^H Op X. rotate() performs X <- X * Q in-place.
Two overloads per function, selected at compile time by the multivector type (most-derived-first):
MultiVectorProductSpaceBlocked (collinear): Blocked loop over S independent N×N sub-problems. Spin-s columns accessed via ptr = X.data() + s*N, lda = S*N — no intermediate copy.
MultiVectorProductSpace (unpolarized S=1 or non-collinear S=2): Single call on the full S*N columns as a coupled unit. S=1 degenerates exactly to the existing scalar path.
scratchXin / scratchXout / scratchXinSmall / scratchXoutSmall for project() are owned by the caller and persist across SCF calls to avoid repeated allocation. All other scratch (SBlock, rotation buffers) is allocated internally per call, consistent with ElpaScalapackOperations.
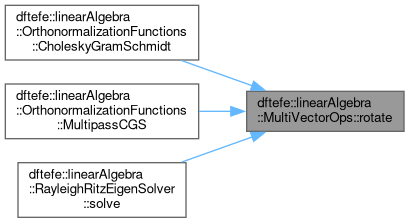
dynamic_cast is NOT performed inside these functions. The caller (RayleighRitzEigenSolver::solve, OrthonormalizationFunctions methods) performs one dynamic_cast per call, then passes the correctly-typed reference here so the compiler selects the right overload.
|
static |
|
static |
|
static |
Coupled overload (unpolarized S=1 / non-collinear S=2, MultiVectorProductSpace).
Computes a single overlap matrix: P = X^H Op X (S*N × S*N) The full S*N columns are treated as a coupled unit. S=1 degenerates to the existing N×N scalar path.
| Op | Operator context. |
| X | Coupled product-space multivector (M × S*N). |
| P | Output: single ScaLAPACK S*N×S*N matrix (pre-allocated). |
| elpa | ELPA/ScaLAPACK manager. |
| scratchXin | Scratch multivector (M × batchSize), caller-owned. |
| scratchXout | Scratch multivector (M × batchSize), caller-owned. |
| scratchXinSmall | Tail-batch scratch, nullptr on first call; cached. |
| scratchXoutSmall | Tail-batch scratch, nullptr on first call; cached. |
|
static |
Blocked overload (collinear, MultiVectorProductSpaceBlocked).
Computes S independent overlap matrices: Ps[s] = Xs^H Op Xs (N×N each) where Xs is the spin-s block of X accessed as ptr = X.data() + s * X.numVectorsPerSpace(), lda = X.numVectors()
| Op | Operator context (e.g. B metric or identity). |
| X | Blocked product-space multivector (M × S*N). |
| Ps | Output: S ScaLAPACK N×N matrices (pre-allocated by caller). |
| elpa | ELPA/ScaLAPACK manager (provides process grid). |
| scratchXin | Scratch multivector (M × batchSize), caller-owned. |
| scratchXout | Scratch multivector (M × batchSize), caller-owned. |
| scratchXinSmall | Tail-batch scratch, nullptr on first call; cached. |
| scratchXoutSmall | Tail-batch scratch, nullptr on first call; cached. |
|
static |
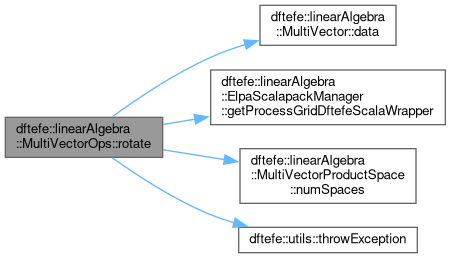
Coupled rotate overload (unpolarized / non-collinear, MultiVectorProductSpace).
Performs a single in-place subspace rotation on all S*N columns: X <- X * Q One M×S*N scratch buffer (unavoidable for in-place operation). S=1 degenerates to the existing scalar rotation path.
| X | Coupled multivector, modified in place. |
| Q | Single rotation matrix (S*N × S*N). |
| elpa | ELPA/ScaLAPACK manager. |
|
static |
Blocked rotate overload (collinear, MultiVectorProductSpaceBlocked).
Performs S independent in-place subspace rotations: Xs <- Xs * Qs[s] using ptr = X.data() + s*N, lda = S*N. scratchRotBlock (M×N) is reused across s iterations — S× smaller than the coupled scratch.
| X | Blocked multivector, modified in place. |
| Qs | S rotation matrices (N×N each). |
| elpa | ELPA/ScaLAPACK manager. |
 1.9.5